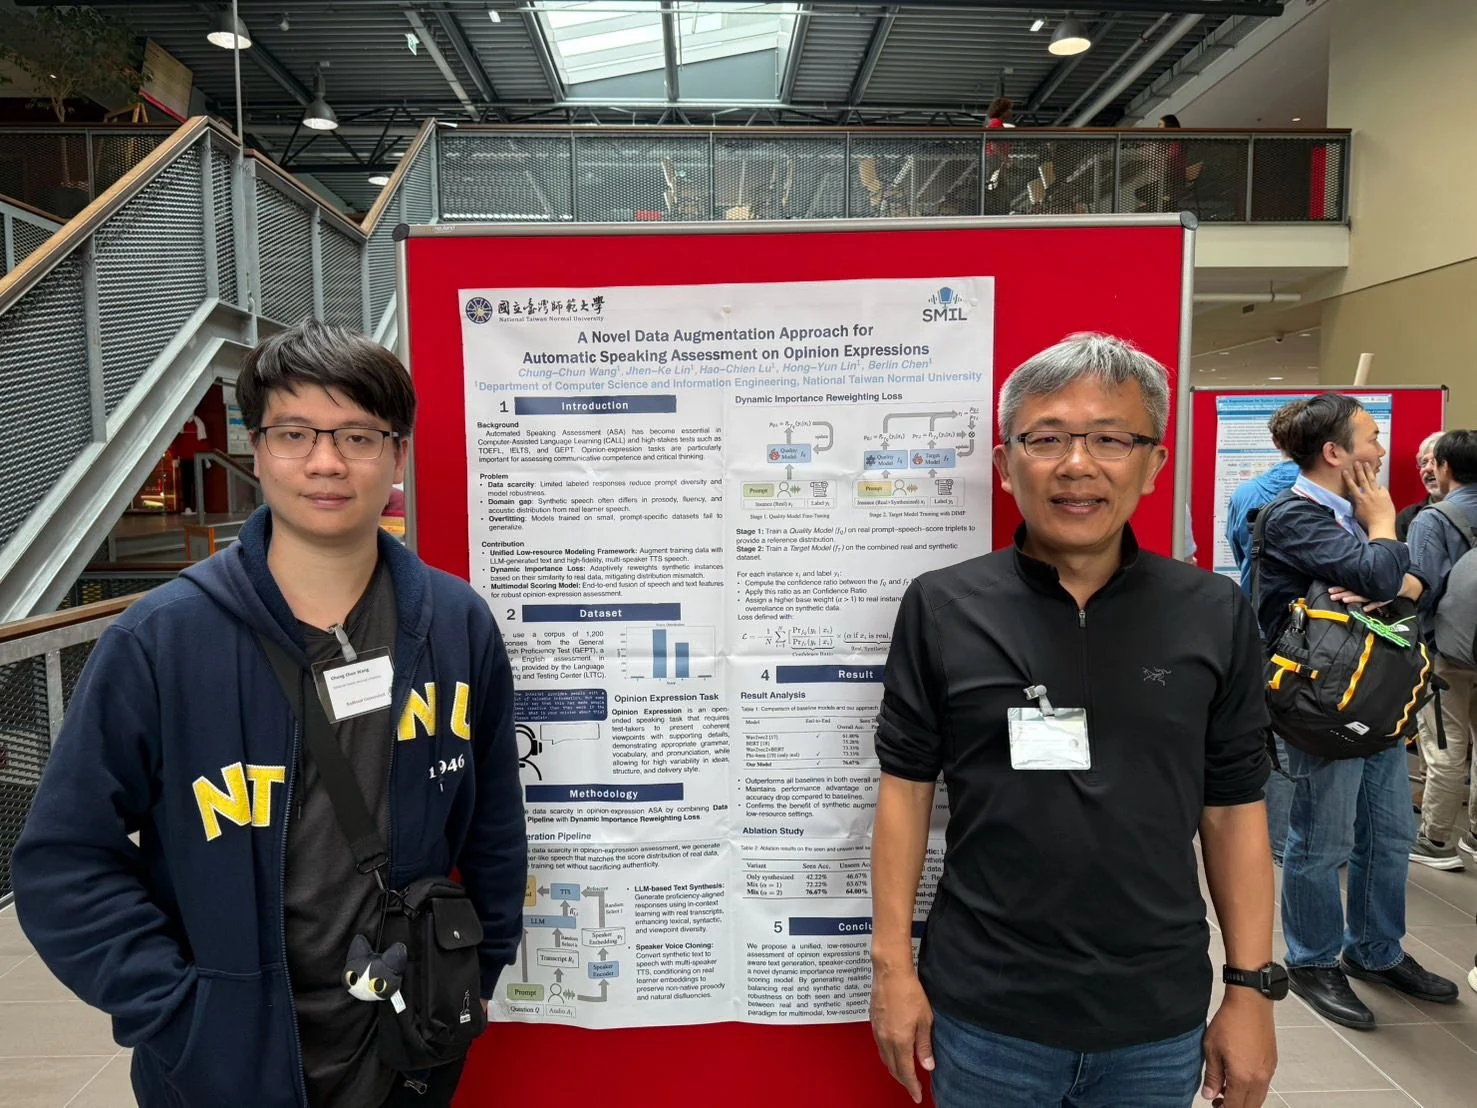
- Publication: 10th Workshop on Speech and Language Technology in Education (SLaTE 2025), pp. 199–203
- My role: First author.
- Problem: Speaking assessment on opinion expressions lacks labeled recordings, which limits prompt diversity and undermines scoring reliability.
- Method: An LLM generates diverse responses at a given proficiency level, speaker-aware TTS synthesizes them into speech, and a dynamic importance loss reweights training instances by the feature-distribution gap between synthesized and real speech; a multimodal LLM then combines text and speech features to predict proficiency scores directly.
- Result: On the LTTC dataset, the approach outperforms methods relying on real data or conventional augmentation, easing the low-resource constraint.